> For the complete documentation index, see [llms.txt](https://help.seoutils.app/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.seoutils.app/guide/serp-clustering.md).

# SERP Clustering

### How Does the SERP Clustering Tool Work?

SEO Utils will cluster your keywords by scraping the search engine results page (SERP). If two keywords share more than four pages in search engine results (**similar results** on SERP), it will group them into a cluster.

Of course, you can adjust the **similar results number** from 3 to 7; the larger the number, the more relevant keywords are in a cluster.

The advantage of this method is that it leverages Google's ability to discern users' search intent. If Google shows many similar pages for two keywords, it indicates that Google recognizes these keywords as having the same search intent.

The only drawback is that it can be time-consuming for large keyword lists, as scraping SERPs is a detailed and cumbersome task.

### How to Cluster Keywords Using SERP Clustering Tool

There are two main processes when the SERP Clustering tool runs:

1. Scraping SERP data for all keywords.
2. Running the [clustering algorithm](#clustering-algorithm) after scrapping all SERP data.

To get started, head to the SERP Clustering in the left sidebar. Then, click the Cluster Keywords button.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-93dcdad10e67de7efccfbde36d175de9198349af%2FXnapper-2024-05-17-21.23.45.png?alt=media" alt=""><figcaption><p>Access the SERP Clustering tool in the left sidebar</p></figcaption></figure>

A modal will be opened; it should look like this. We will go over each setting one by one.

<div data-full-width="true"><figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-e8343a16158a4589fa91edf9859c95d041e0567f%2FXnapper-2024-06-24-21.54.51.png?alt=media" alt=""><figcaption><p>SERP Clustering modal</p></figcaption></figure></div>

#### Keyword Files

SERP Clustering tool that lets you upload multiple files. It automatically combines the keywords and removes any duplicates. No need to mess with Excel anymore. This will save you some time.

After uploading files, you need to map the columns

* **Keyword column:** This column is required.
* **Search Volume column:** This is optional. You can map your external search volume, so you don't have to re-check the search volume for your keywords.

To map columns, click on the Column dropdown.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-80e3bdd14d2916c29cc7c0f283d27b1fdfb253ab%2FXnapper-2024-05-17-21.35.41.png?alt=media" alt=""><figcaption><p>Map the keyword column</p></figcaption></figure>

{% hint style="info" %}
SEO Utils also automap columns if your files have a guessable column name.
{% endhint %}

{% hint style="success" %}
**Updated:** Since version 1.6.0, you can also map CPC and search intents columns.
{% endhint %}

#### Location / Language

Select the location that you want to target and the language of your keyword lists. SEO Utils uses this field for checking keyword search volume in most cases.

#### Geo Target (Optional)

This field allows for more precise geotargeting when scraping SERP. You can type a specific location like a city, country, etc.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-8cbe993c4fb45c5d4e53828a931d408f65931d47%2FXnapper-2024-05-17-21.43.37.png?alt=media" alt=""><figcaption><p>You can type a city name like Seattle</p></figcaption></figure>

{% hint style="info" %}
When using this field, SEO Utils will ignore the location that you selected from the **Location / Language** field.
{% endhint %}

#### Desktop Devices

SEO Utils will check search results for desktop devices. If you want to check for mobile devices, please disable this setting.

#### Check Keyword Metrics

SEO Utils will use DataForSEO to check keyword metrics. This helps determine the **primary keyword** for a cluster, so it's recommended to enable this setting.

However, if your uploaded files already have search volume data and you mapped the Volume or CPC column, you can turn off this setting to save money.

{% hint style="info" %} <mark style="color:blue;">**Tip**</mark>: If your uploaded files don't have enough search volume data for all keywords, you can turn on the "Check Search Volume" field. SEO Utils only check the search volume for **keywords that are missing data**.
{% endhint %}

#### Cluster Strategy

When setting the primary keyword for clusters, SEO Utils will use the keyword that has the most search volume in a cluster, however, some users have mentioned that setting the primary keyword for a cluster based on Cost Per Click (CPC) provides better results when your keywords are transactional or commercial. You can now select the Cluster Strategy to use CPC instead.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-5f6567f31af78099f8d0af7b40a997789531feda%2FXnapper-2024-06-20-15.58.20.png?alt=media" alt=""><figcaption><p>Using CPC to set the primary keyword for clusters.</p></figcaption></figure>

#### Clustering Algorithm

Since [version 1.30.0](https://help.seoutils.app/changelog#v1.30.0), SEO Utils offers three different clustering algorithms to suit different needs:

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-59ff9382ca49cc2a3aa345f02da9299a5c3c1c28%2FCleanShot%202025-05-28%20at%2012.01.49%402x.png?alt=media" alt=""><figcaption><p>Select the clustering algorithm that best fits your needs</p></figcaption></figure>

**Default Algorithm**

* Groups keywords if they share X URLs with the primary keyword (highest search volume/CPC)
* Creates broader topic clusters
* Best for content hubs and category planning
* Fastest processing speed

**Strict Algorithm**

* Groups keywords only if ALL keywords in the cluster share X URLs with each other
* Creates very tight, highly relevant clusters
* Best for precise content targeting
* **Limitation**: May result in many single-keyword clusters due to "first-mover advantage"

**Balanced Strict Algorithm**

* Solves the Strict algorithm's limitation by using progressive thresholds
* Small clusters (2-5 keywords): requires 100% match (like Strict)
* Medium clusters (6-10): requires 80% match
* Large clusters (11+): requires 60% match
* **Why it's needed**: Prevents clusters from becoming "too strict" as they grow larger
* Best balance between quality and natural cluster growth

{% hint style="info" %} <mark style="color:blue;">**Why Balanced Strict was created**</mark>: The original Strict algorithm has a "first-mover advantage" problem where early keywords easily join clusters, but later keywords struggle to match ALL members in larger clusters. This often results in many single-keyword clusters. Balanced Strict solves this by relaxing requirements as clusters grow, allowing natural expansion while maintaining quality.
{% endhint %}

{% hint style="info" %} <mark style="color:blue;">**How to Choose**</mark>:

* **Default**: When you need broad topic grouping or have 100,000+ keywords
* **Strict**: When you need very precise clusters for competitive niches
* **Balanced Strict**: When you want quality clusters that can still grow naturally (recommended for most users)
  {% endhint %}

**Processing Time Comparison**

The more advanced algorithms take longer to process due to additional quality checks:

| Dataset Size     | Default Algorithm | Strict/Balanced Strict | Time Difference |
| ---------------- | ----------------- | ---------------------- | --------------- |
| 1,000 keywords   | 1-2 seconds       | 3-5 seconds            | 2-3x slower     |
| 10,000 keywords  | 5-10 seconds      | 15-30 seconds          | 2-3x slower     |
| 50,000 keywords  | 1-2 minutes       | 5-10 minutes           | 3-5x slower     |
| 100,000 keywords | 5-10 minutes      | 20-40 minutes          | 4-5x slower     |

{% hint style="warning" %} <mark style="color:orange;">**Performance Note**</mark>: Strict and Balanced Strict algorithms require more processing time but produce higher quality clusters. For very large datasets (100,000+ keywords), consider using the Default algorithm or breaking your keywords into smaller batches.
{% endhint %}

{% hint style="success" %}
SEO Utils' clustering algorithm is designed to handle large-scale keyword datasets efficiently. You can cluster between 50,000 to 200,000 keywords at once—a capability not many tools on the market offer. Most other tools typically allow clustering of only 5,000 to 10,000 keywords at a time.
{% endhint %}

#### Similar Results on SERPs

The value range is from **3 to 7**. For example, if you set this field to 4, SEO Utils will group 2 keywords into a cluster if they have at least **4 common URLs on SERPs**. The larger the number, the more relevant keywords are in a cluster.

{% hint style="info" %} <mark style="color:blue;">**Tip**</mark>: The recommended value is 4, but you are free to test a different value by using the ["Re-cluster keywords" button](#re-cluster-keywords).
{% endhint %}

#### Use Saved SERP Data For X Days

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-d208a3b081a9949f3e57a2861ee33b7b2603a718%2FXnapper-2024-05-17-22.01.13.png?alt=media" alt=""><figcaption></figcaption></figure>

Enter the number of days you wish to use previously saved SERP data. By setting this duration, you can speed up the clustering process and save money as SEO Utils will reuse existing data without the need to re-scrape.

Choose a number that best balances freshness of data with processing speed.

Set '0' to always scrape fresh SERP data.

{% hint style="info" %} <mark style="color:blue;">**Tip**</mark>: This field is a great method for testing **Similar Results on SERPs** value since you don't have to re-scrape SERP data for all keywords.
{% endhint %}

#### Reuse SERPs for Word-Order Twins

Some keywords use the same words in a different order, for example **"laravel horizon"** and **"horizon laravel"**. We call them **word-order twins**. Google usually shows almost the same results for both, so SEO Utils can scrape the SERP once and reuse it for the twin.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2FxHeQumoBbRMkq3z7w8wm%2FXnapper-2026-09-18-16.36.23.png?alt=media&amp;token=25d8f96f-da5f-41eb-ae7b-2b6b8fb5bc30" alt="The Reuse SERPs for word-order twins switch in the Cluster Keywords modal" width="563"><figcaption><p>Turn on "Reuse SERPs for word-order twins" to scrape one SERP per twin group</p></figcaption></figure>

When this setting is on:

* In each group of twins, SEO Utils scrapes the SERP for **one keyword only**. The other keywords in the group use that SERP for clustering.
* If a twin already has recent saved SERP data (see **Use Saved SERP Data For X Days**), it keeps its own data. SEO Utils reuses a SERP only instead of scraping a new one.
* The setting works with every scraping method. With the SERP API it saves money; with your own IP or proxies it sends fewer requests.

The setting is **off by default**. Turn it on for each run where you want to use it.

**Should you turn it on?**

|               |                                                                                                                                                         |
| ------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Savings**   | In our tests, 6–16% of keywords were twins. That saves roughly **$0.60–$1.70 per 10,000 keywords** at normal priority, and twice that at high priority. |
| **Accuracy**  | 136 of 137 tested twins really did share their Google results.                                                                                          |
| **Trade-off** | On a 1,503-keyword list, about **18 in 100 keywords** ended up in a slightly different cluster than when every SERP was scraped.                        |

{% hint style="warning" %} <mark style="color:orange;">**Word order can change the meaning**</mark>: This is rare, but it happens. For example, "keychron numpad" shows videos and DIY posts, while "numpad keychron" shows the brand's shop pages. If exact clusters matter more than the savings, keep this setting off.
{% endhint %}

{% hint style="info" %}
A reused SERP is used for clustering only. SEO Utils never shows it as the twin's own Google results. See [Reused SERPs in Your Report](#reused-serps-in-your-report).
{% endhint %}

#### Scrape SERP With

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-99a76fe75585b8b0fb0692c21a85d73afeb33b9b%2FXnapper-2024-05-17-22.03.02.png?alt=media" alt=""><figcaption><p>Select a method to scrape SERP</p></figcaption></figure>

There are 3 options for now:

* **My IP:** SEO Utils use your IP to scrape SERP data. This is not recommended if you have over 100 keywords.
* **Proxies:** Use proxies to scrape SERP data. See how to set up a proxy [here](/guide/how-to-use-proxies.md).
* **SERP API: DataForSEO:** Use SERP API from DataForSEO to scrape SERP data.

We will focus on Proxies & SERP API, so you can determine which method is best fit for you.

**SERP API Method**

DataForSEO provides a reliable API to scrape SERP data with 3 modes:

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-d6e6a4aa0effc3cbf528b89f3f88e2397b57d460%2FXnapper-2024-05-17-22.10.22.png?alt=media" alt=""><figcaption><p>3 modes</p></figcaption></figure>

Since the Live mode is expensive, so SEO Utils doesn't support it. After selecting the SERP API method, you will able to select the mode in the **Priority** field.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-cf4afaa5a4acb399e0804627d4a00492e1f9bf87%2FXnapper-2024-05-17-22.11.57.png?alt=media" alt=""><figcaption><p>Select a mode</p></figcaption></figure>

I recommend using the **normal execution priority (Standard Queue)** option. I have tested to cluster 2,000 keywords, and it only took about 12 minutes to finish all processes. [See the video here](#video-running-serp-clustering-on-2-000-keywords-with-serp-api).

It only costs **$0.6 to scrape SERP & cluster 1,000 keywords**. This rate is much cheaper when compared to other tools on the market, which usually cost **$7-$12 for 1,000 keywords**.

Yes, you read that right! It's 11 times cheaper:v:.

{% hint style="info" %}
In v1.21.0, I added a cost estimation tool for the SERP API, allowing you to see the actual cost after deducting keywords that use saved SERP data. Please [click here](#cost-estimation-tool-for-serp-api-method) to learn more about it.
{% endhint %}

{% hint style="warning" %}
**Important:**

To use the SERP API, you must have your own DataForSEO account. [Renting API key services](/guide/rent-dataforseo-api-key.md) isn't viable because DataForSEO restricts certain endpoints that I utilized to implement the Queue mode. If multiple users rely on a rented API key from my account, it will slow down the process for everyone. For the quickest results, using your own DataForSEO account is the best approach.
{% endhint %}

**Proxies Method**

If you need to cluster 1 million keywords per month, using the SERP API Method would indeed be costly, amounting to $600.

This is where the Proxies method becomes valuable. By using your own proxies, you can significantly reduce the costs associated with such large-scale keyword clustering.

You can pay about **$80-$100** per month for a rotating residential proxy and you can cluster **millions of keywords**.

However, this method has more fields to set up.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-723be5926171b2b048e8d413de228026e10a1b9e%2FXnapper-2024-05-17-22.50.14.png?alt=media" alt=""><figcaption><p>3 important fields for Proxies method</p></figcaption></figure>

**Workers**

This is the number of concurrent requests SEO Utils will scrape SERP. You can enter from 1-50. If you have a good proxy provider, you can set it to 50 (my setting), so SEO Utils can send 50 requests in one second to scrape SERP data. This will increase the clustering process a lot.

If you are unsure about your proxy quality, go with 5-10 workers first.

**Request Delay**

Enter the number of seconds you wish to have between each request to scrape SERP data for keywords. The more delay time you set, the slower the process will be, but it will help you avoid being blocked by Google.

Set '0' to scrape SERP data without any delay.

{% hint style="success" %}
For example, if you set **Workers** to 10 and **Request Delay** to 1 second. SEO Utils will send 10 requests and then sleep for one second before sending another 10 requests.
{% endhint %}

**Back-off Time**

Enter the number of seconds you wish to wait before retrying the failed scraping request. SEO Utils retries the request up to 3 times before skipping a keyword. The more back-off time you set, the slower the process will be, but it will help you avoid being blocked by Google.

{% hint style="success" %}
For example, if you set **Workers** to 10, **Request Delay** to 1 second, and **Back-off Time** to 2 seconds. SEO Utils will send 10 requests and then sleep for one second before sending another 10 requests.\
\
However, while processing, if one request in 10 requests is failed, it will sleep for **2 seconds (back-off time)** before retrying the failed request.
{% endhint %}

{% hint style="info" %}
SEO Utils will retry a maximum of **three times** before skipping scraping a keyword. That keyword will end up with no SERP data.
{% endhint %}

{% hint style="info" %}
If you set the **Back-off Time** to '0', SEO Utils will use the default back-off time:

* 1 second for the 1st attempt
* 2 seconds for the 2nd attempt.
* 3 seconds for the 3rd attempt.
  {% endhint %}

Feel free to experiment with different settings for your proxies and usage. When testing these settings, as long as you don't encounter a "Too Many Requests" error message, it should indicate that your setup is functioning correctly.

\
Since SEO Utils automatically retries each request up to three times, you might see a message like:

`Attempt 1 failed to scrape SERP for keyword 'keyword': failed to visit URL: Too Many Requests.`

Don't worry if you see this message. SEO Utils will try two more times, so everything is still fine unless you see a failure message on the third attempt.

| SERP API                                                | Proxies                                                |
| ------------------------------------------------------- | ------------------------------------------------------ |
| Use when clustering **thousands** of keywords per month | Use when clustering **millions** of keywords per month |
| Less configuration and testing                          | More configuration and testing                         |

### Re-cluster Keywords

After clustering keywords, you can visit the report and re-cluster keywords.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-87d3c06f68c85f46e3c4f6c6a86f7f386a4e242e%2FXnapper-2024-05-17-23.20.37.png?alt=media" alt=""><figcaption><p>Click the Re-cluster Keywords button to re-cluster all keywords in the report</p></figcaption></figure>

You might need to re-cluster keywords in the following situations:

* When testing the **Similar Results field on SERPs** field.
* If you're adding more keywords to a report and need to cluster them with existing ones.
* To monitor the clusters before and after Google Core Updates to observe any impact.
* If some keywords are missing SERP data because some SERP scraping requests were failed.

SEO Utils will show this message if some keywords in your report are missing SERP data, so you know to re-run the clustering process.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-fd9b960abadcb843384f44a9edabdef7ae1202f0%2FXnapper-2024-05-17-23.28.20.png?alt=media" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
When re-clustering keywords, make sure you use the "[**Use Saved SERP Data For X Days**](#use-saved-serp-data-for-x-days)" field. This ensures that SEO Utils won't re-scrape SERP data, saving time and resources.
{% endhint %}

#### Consistent Results

Re-clustering the same keywords with the same SERP data and the same settings always gives the same clusters. This is true for all three [clustering algorithms](#clustering-algorithm).

When two keywords have the same search volume (or CPC) and the same number of words, the keyword that comes **first in your keyword list** becomes the primary keyword of the cluster.

#### Distribute Keywords into Existing Clusters (Available since v1.16.0)

When re-clustering keywords, you'll be able to distribute new and non-clustered keywords into existing clusters, rather than rebuilding all clusters from scratch.

This is particularly useful if you've already used clusters to create articles on your website and you just want to add new keywords to existing articles (clusters).

A **"New" badge** will highlight these newly added keywords, and a **"Run #" label** will indicate which clustering run they were added in.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-d25093551ef46742a80feaeab2e644d55c676ae4%2F448666243_7699027523499742_768845294393561290_n.jpg?alt=media" alt=""><figcaption><p>Enable the setting to distribute keywords into existing clusters</p></figcaption></figure>

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-a022a013fa2bae135fdea290f0edfea0aa0b1114%2F448646536_7699027720166389_2702349076745059710_n.jpg?alt=media" alt=""><figcaption><p>The "New" badge will help you determine the latest keywords just added to a cluster.</p></figcaption></figure>

### Reused SERPs in Your Report

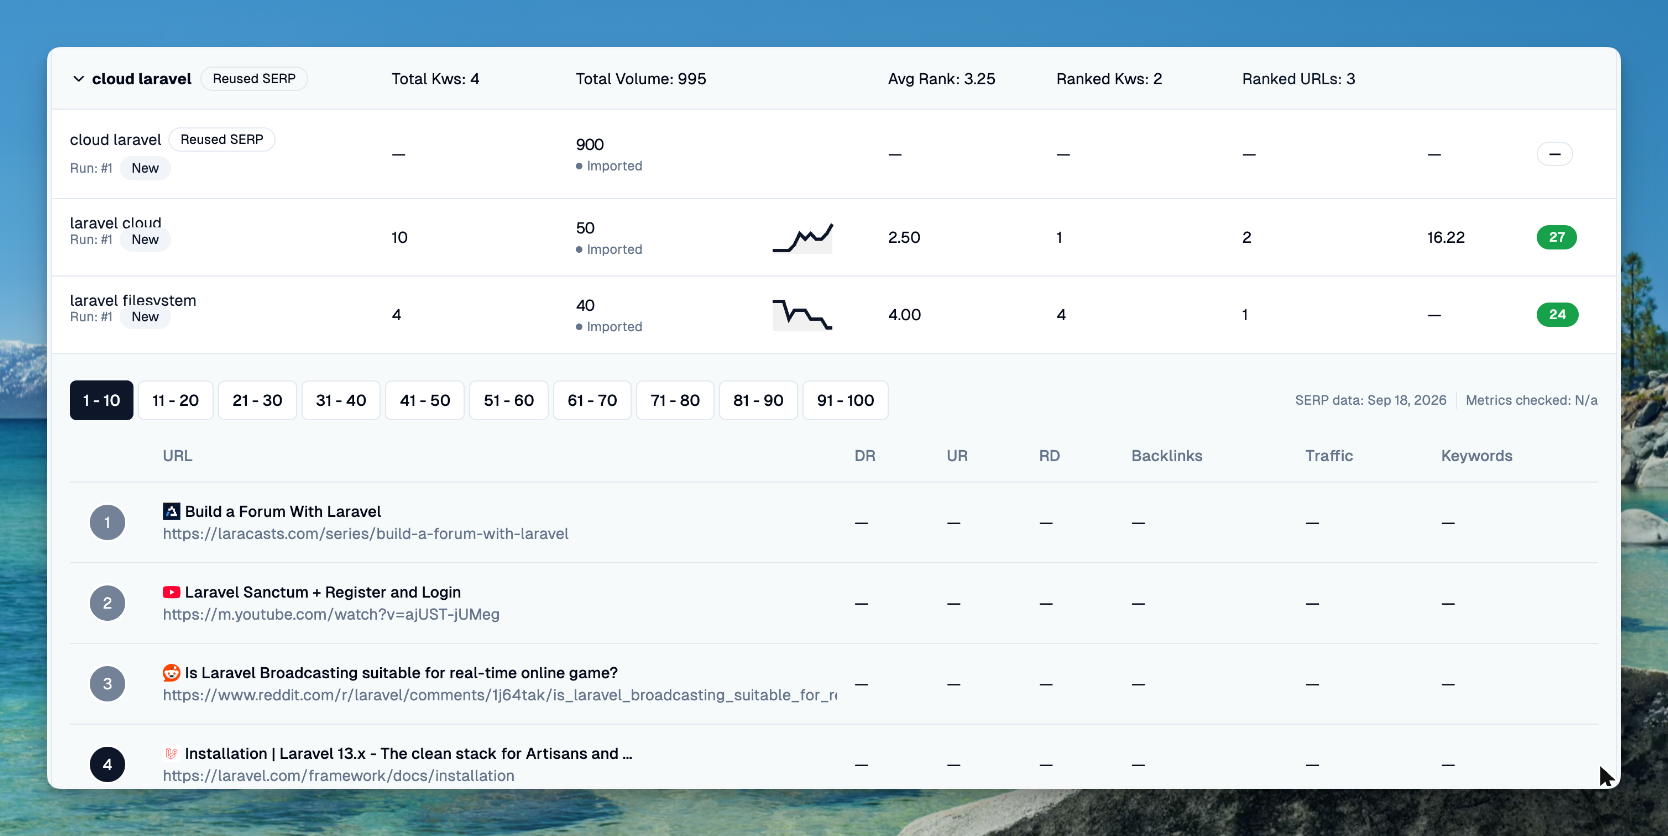
When a run uses [Reuse SERPs for Word-Order Twins](#reuse-serps-for-word-order-twins), the report tells you clearly which keywords did not get their own SERP.

#### Report Summary

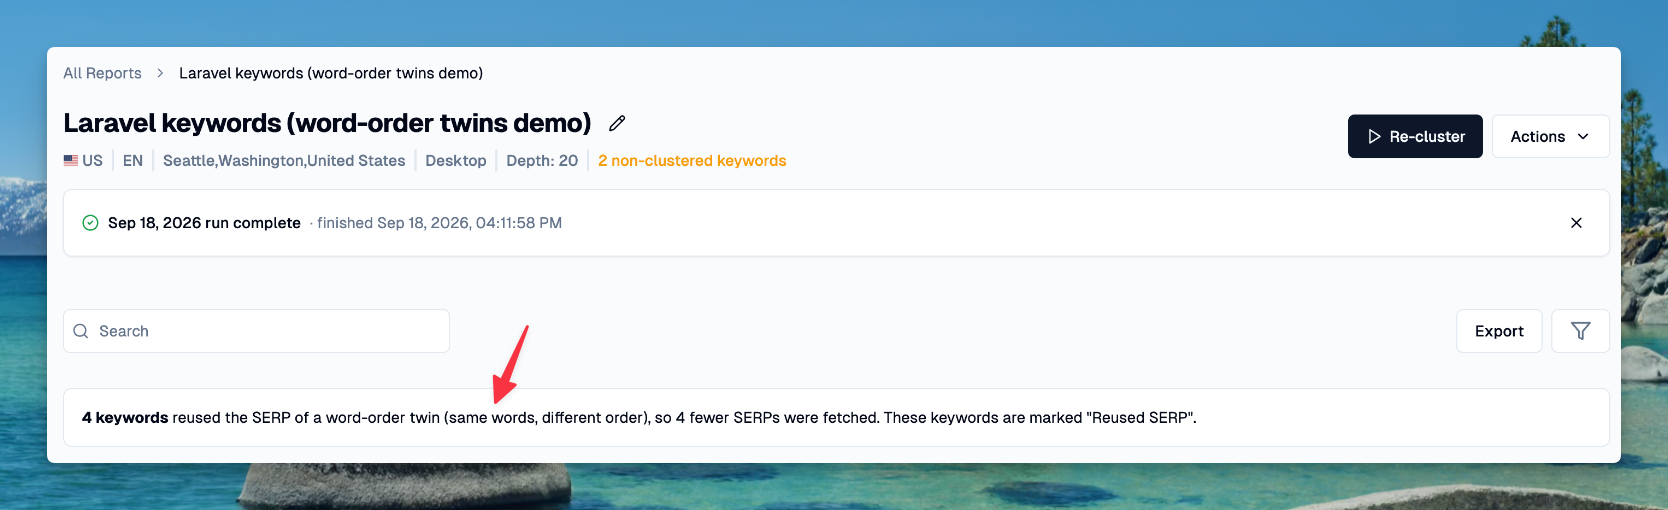
A line above the table shows how many keywords reused a twin's SERP, and so how many fewer SERPs were scraped.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-486a4dd84596dedfa3ce169175452e79e79b6332%2Fserp-clustering-reused-serp-summary.png?alt=media" alt="The reused SERP summary line above the clusters table"><figcaption><p>The summary line shows how many keywords reused a twin's SERP</p></figcaption></figure>

#### The "Reused SERP" Badge

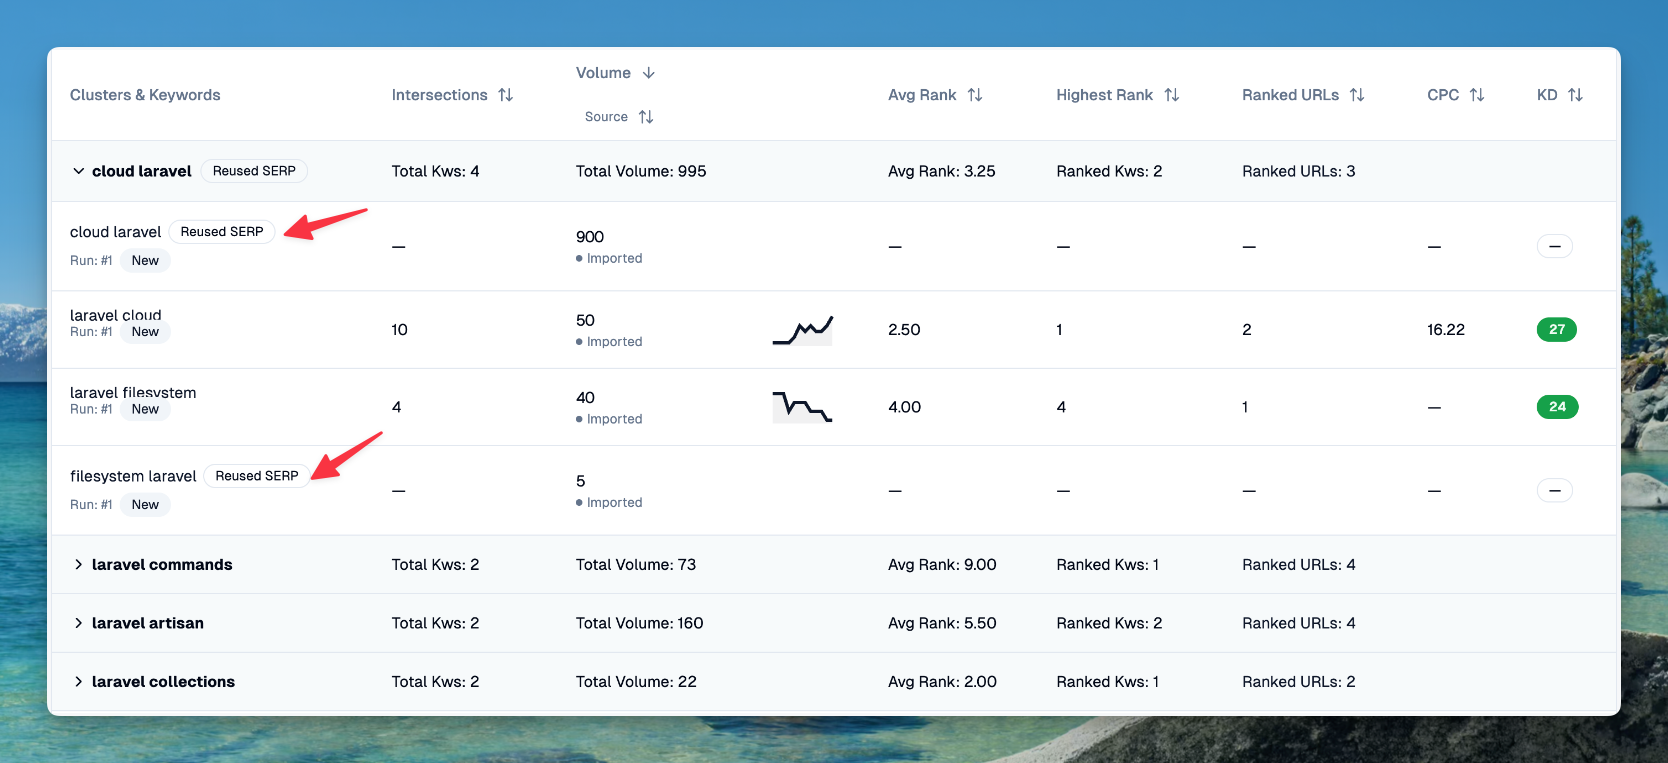
Each keyword that reused a SERP has a **Reused SERP** badge next to its name. The badge also shows on the cluster row when a reused keyword is the primary keyword of the cluster.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-97c5299a01f9094a583a4d6ef00ad1c4c2e94ef3%2Fserp-clustering-reused-serp-badges.png?alt=media" alt="Keywords with the Reused SERP badge in the clusters table"><figcaption><p>Reused keywords have a badge, and their SERP-based columns show a dash</p></figcaption></figure>

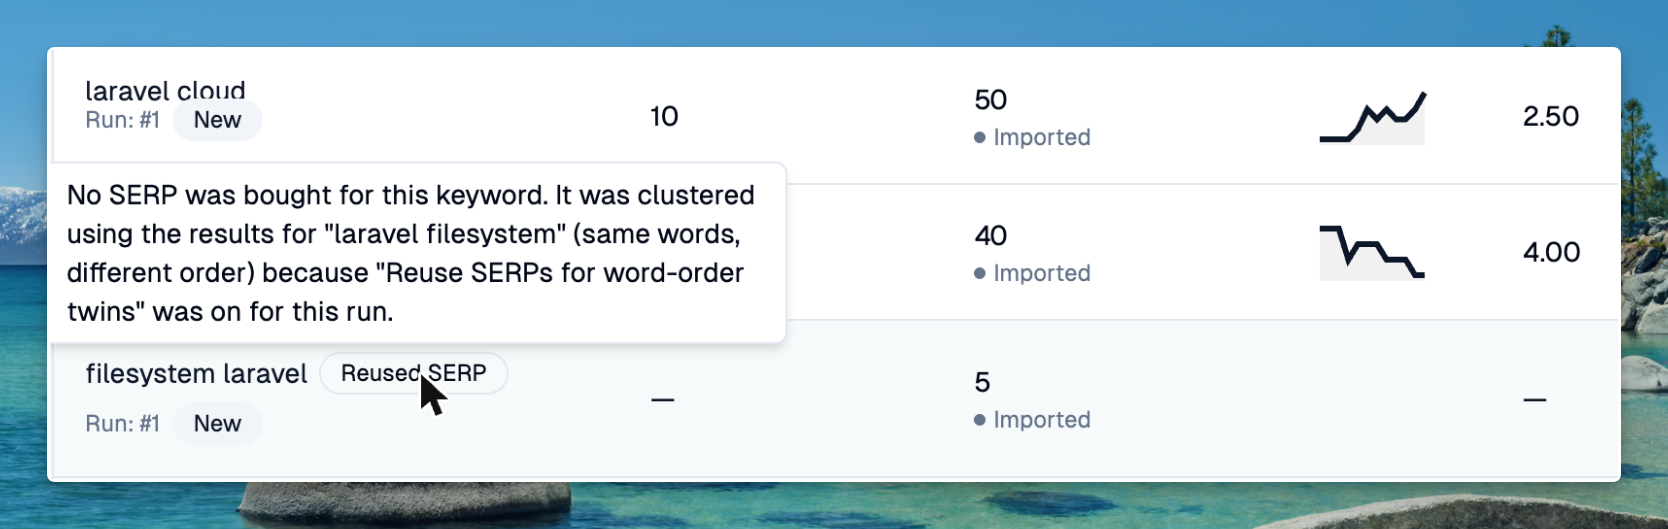
Hover over the badge to see which keyword's results were used.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-f6054e75010024856f2fc90ea174021f3262e82b%2Fserp-clustering-reused-serp-tooltip.png?alt=media" alt="Tooltip of the Reused SERP badge"><figcaption><p>The badge tooltip names the twin whose results were used</p></figcaption></figure>

For a reused keyword, these columns show a dash (**—**), because the keyword has no SERP of its own:

* Intersections
* Avg Rank
* Highest Rank
* Ranked URLs

Reused keywords are also left out of the cluster's **Avg Rank**, **Ranked Kws** and **Ranked URLs** totals, so one SERP is never counted twice.

#### Viewing a Reused Keyword

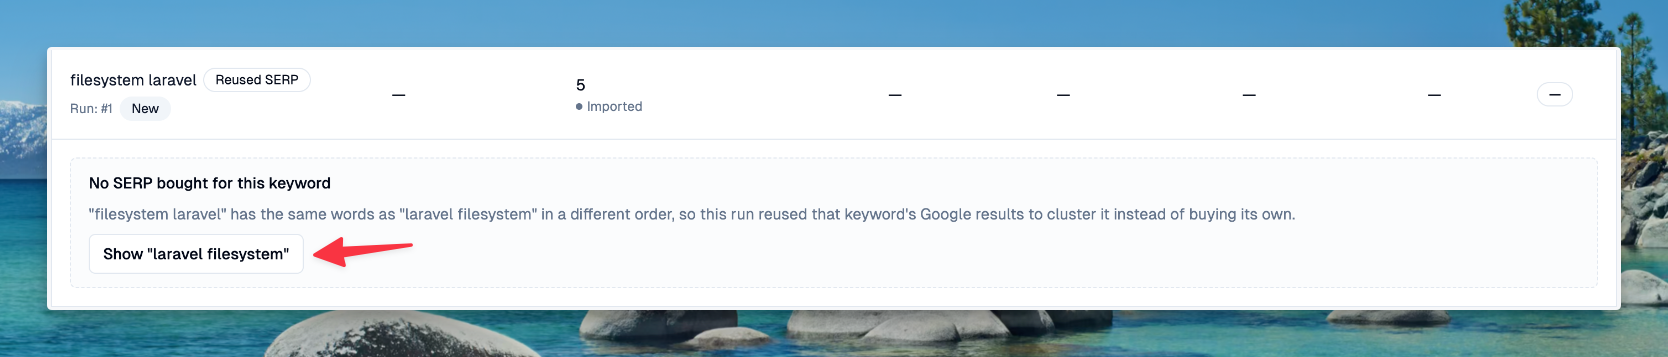
Click a reused keyword to expand it. Instead of a SERP table, you see a **"No SERP bought for this keyword"** message that names its twin.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-59a699adc93d8695cffc6673c3dc7593ac183782%2Fserp-clustering-no-serp-bought-panel.png?alt=media" alt="The No SERP bought for this keyword message"><figcaption><p>A reused keyword shows a message instead of a SERP table</p></figcaption></figure>

Click **Show "\<twin keyword>"** to go to the twin's own row. SEO Utils expands it, scrolls to it and highlights it for a moment, so you can see the SERP that was used for clustering.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-1ce85c58d536953d5695bab894e2bcaee3116a7e%2Fserp-clustering-show-source-row.png?alt=media" alt="The twin&#x27;s row expanded with its SERP"><figcaption><p>The twin's row opens with its own Google results</p></figcaption></figure>

{% hint style="info" %}
If the twin is not in the list you are viewing (for example, it is on another page, hidden by your search, or in another cluster), SEO Utils opens a panel with that keyword only. Click **Show all keywords** in the panel to see the rest of its cluster.
{% endhint %}

{% hint style="success" %}
To get a keyword's own SERP again, re-cluster the report with **Reuse SERPs for word-order twins** turned off. SEO Utils then scrapes a SERP for every former twin (unless it has recent saved data) and removes the badges.
{% endhint %}

### Analyzing SERP

After clustering your keywords, you can analyze the SERPs of the clustered keywords to see how your competitors are performing. This analysis can show you their monthly traffic, the keywords they rank for, and how many backlinks they have.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-efd836eabbf0ab7e219e4e1994974a03f4fb4f61%2FXnapper-2024-05-18-12.34.29.png?alt=media" alt=""><figcaption><p>Click the vertical three dots icon to start analyzing SERP</p></figcaption></figure>

You can choose the type of metric and specify the number of URLs on the SERP for each keyword you want to run the analysis for.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-729bca15ce07540fb7784f60943031f998710165%2FXnapper-2024-05-18-12.38.31.png?alt=media" alt=""><figcaption><p>Analyze SERP for selected keywords</p></figcaption></figure>

After analysis, you can click on a keyword to view the SERP data with all metrics including traffic, backlinks, referring domains, spam score, keywords, etc for that keyword.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-e4577ba59fb61b64f984b0fa18d3bc668cbc01cf%2FXnapper-2024-05-18-12.44.50.png?alt=media" alt=""><figcaption><p>SERP data for the keyword "vodka cocktails," including backlinks and traffic data</p></figcaption></figure>

The analyzed data is also included in the exported file under the second tab labeled "SERP Data."

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-ab1352bc9e0ca8208b7fce4fe013fd27827ef585%2FXnapper-2024-05-18-12.54.08.png?alt=media" alt=""><figcaption><p>All backlinks &#x26; traffic data are included in the SERP data sheet</p></figcaption></figure>

{% hint style="info" %}
Keywords that [reused a twin's SERP](#reused-serps-in-your-report) are skipped by the analysis and are not counted in its cost, because they have no SERP of their own. Their twin is analyzed as usual.
{% endhint %}

In the exported file, reused keywords work the same way:

* The **Keyword Clusters** and **Non-Clustered Keywords** sheets have a **SERP Source** column. It is empty for a keyword with its own SERP, and shows the twin's keyword for a reused keyword.
* For a reused keyword, the intersection and rank cells are empty.
* The **SERP Data** sheet has no rows for reused keywords.

### Ranking Data

You can add a target domain to a SERP Clustering report. This will show you the ranking data of that domain across all clusters, helping you identify which clusters you are ranking well in and which ones need improvement. This feature allows you to prioritize your efforts to boost your rankings effectively.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-c2aa888d480ff7ae83d971dee3a611312136e59e%2FXnapper-2024-06-21-16.48.38.png?alt=media" alt=""><figcaption><p>Ranking data will be shown in the table after adding a target domain</p></figcaption></figure>

When viewing the SERP of a keyword, the target domain will be marked in green color.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-827bba9675bbfe6c1aa516048455951e1188819b%2FXnapper-2024-06-21-16.49.10.png?alt=media" alt=""><figcaption><p>Target domain in SERP table</p></figcaption></figure>

{% hint style="success" %}
**Tip:** You can also change the target domain to a competitor's domain to see how well they are performing across different clusters. This can help you identify their strengths and areas where you might have an advantage.
{% endhint %}

SEO Utils also provides some metric cards to show you the cluster's key ranking data at a glance:

* View and filter the number of ranking clusters.
* View and filter the number of clusters without rankings.
* See and filter the rank distribution across clusters.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-9fee993b06494fbf1f26de946783f38409b109dd%2FCleanShot%202024-06-23%20at%2022.35.45%402x.png?alt=media" alt=""><figcaption><p>Metric cards and filters</p></figcaption></figure>

You can watch the video below to see the "Ranking Data" feature in action.

{% embed url="<https://drive.google.com/file/d/1se5GGf6U5Fzrhuv3GlZBAzPCrSBMlG25/view?usp=drive_link>" fullWidth="true" %}

### Cost Estimation Tool for SERP API Method

When using the SERP API to scrape SERP data, you can click the “Estimate Cost” button to view the actual cost. SEO Utils will read all keywords in your uploaded file, remove duplicates, and exclude keywords that already have saved SERP data, providing you with an accurate final cost.

In the screenshot below, I uploaded over **18,000 keywords** and used SERP data from the past 7 days. The cost came to just **$0.0390**, saving me **$11.2470**! SEO Utils only sent **65 keywords** to the SERP API for new data, as most of the keywords already had recent SERP data within 7 days.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-fc3800a5525db616bd73013b49b0287268edced0%2F464919090_8563919223677230_7461303937806986891_n.jpg?alt=media" alt=""><figcaption><p>Cost estimation tool for SERP API.</p></figcaption></figure>

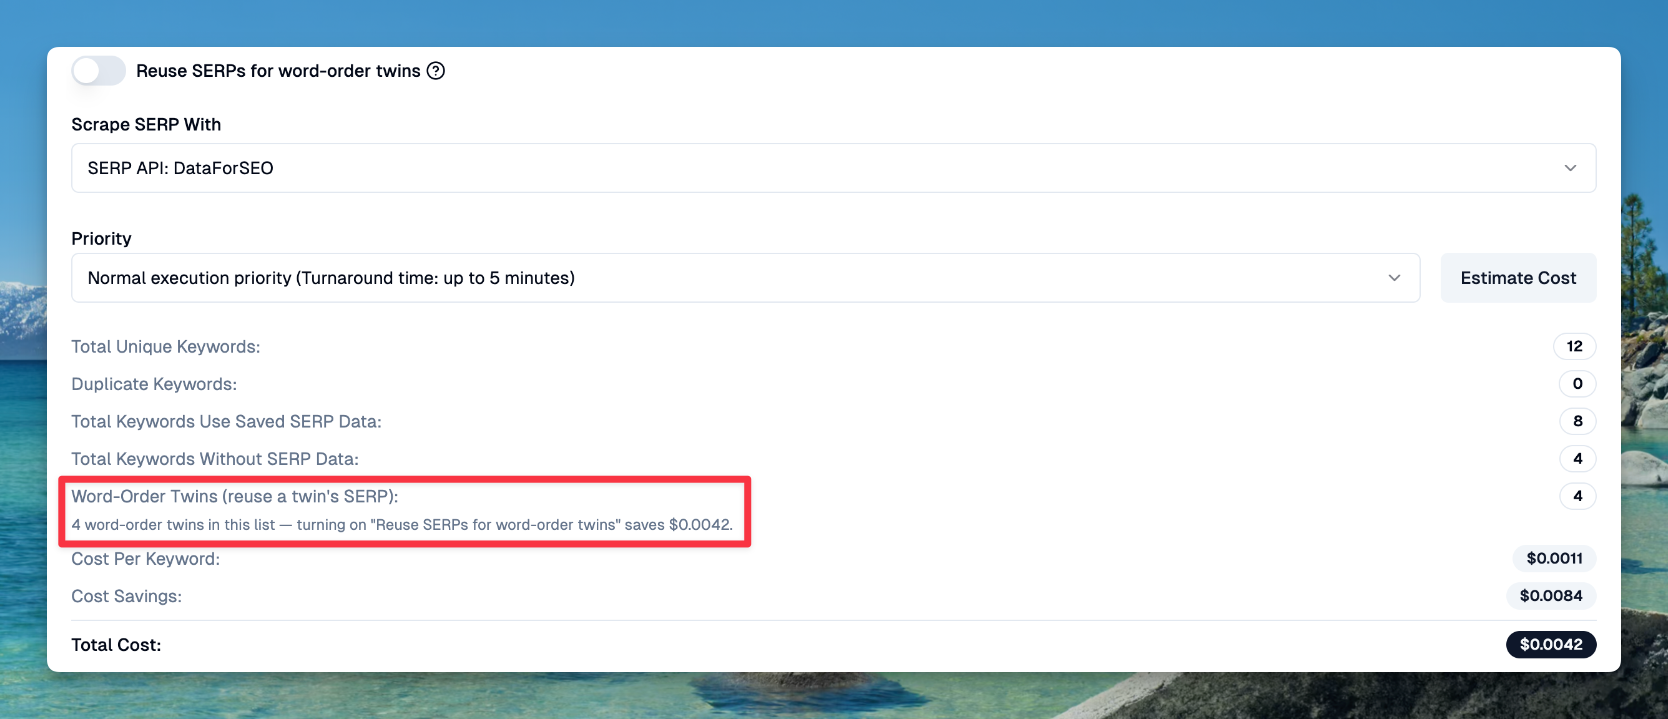
The estimate also counts the **word-order twins** in your list, even when [Reuse SERPs for Word-Order Twins](#reuse-serps-for-word-order-twins) is off. Use it to decide whether to turn the setting on for this list:

* **Setting off:** the estimate shows how many twins your list has and how much turning the setting on would save.
* **Setting on:** the saving is already taken out of the **Total Cost**.

<figure><img src="https://1176579443-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F2DwV6sJBiKjUHMDggb4d%2Fuploads%2Fgit-blob-0b84077f094b2b57b88e96b59d1ae6c0cb599811%2Fserp-clustering-word-order-twins-estimate.png?alt=media" alt="Cost estimate with the Word-Order Twins line"><figcaption><p>The estimate shows the twins in this list and what reusing their SERPs saves</p></figcaption></figure>

{% hint style="info" %}
The cost estimate is available in the desktop app. In a remote browser, the report shows the real number of reused SERPs after the run.
{% endhint %}

### Video Running SERP Clustering on 2,000 keywords with SERP API

{% embed url="<https://drive.google.com/file/d/1UJr9PD-t2XNjRmaKL1VP840XajQoStV7/view?usp=sharing>" %}
Demo on clustering 2000 keywords
{% endembed %}